OpenRouter প্রোভাইডার রাউটিং: মডেলের মান, টোকেন সীমা এবং প্রকৃত খরচ
Table of Contents
OpenRouter provider routing নির্ধারণ করে কোন inference service আপনার অনুরোধের উত্তর দেবে। একই model name ব্যবহার করা দুইটি call-ও endpoint limit, সমর্থিত parameter, serving software এবং routing preference-এর ওপর নির্ভর করে। উত্তর ছোট হলে বা tool call ব্যর্থ হলে quantization-কে দোষ দেওয়ার আগে এই পার্থক্য পরীক্ষা করুন।
প্রধান বিষয়
- Precision label একটি সংখ্যাগত format বোঝায়, উত্তরের accuracy score নয়।
- Endpoint limit context, output length এবং feature support নির্ধারণ করে।
- Explicit routing-এর জন্য provider preference-এর পাশাপাশি fallback policy দরকার।
- Auto Exacto quality signal ব্যবহার করে provider নির্বাচন উন্নত করে এবং tool-বিহীন অনুরোধের জন্য opt-in route দেয়।
- কার্যকর খরচে output, cache behavior, retry এবং সফল task completion অন্তর্ভুক্ত।
প্রয়োজনীয়তা: JSON request সম্পর্কে ধারণা এবং আপনার application-এর OpenRouter configuration-এ প্রবেশাধিকার। Endpoint inspection একটি public API ব্যবহার করে। Model request পাঠাতে API key এবং usage charge দরকার। পুরনো উদাহরণ পুনরায় ব্যবহারের আগে endpoint metadata পরীক্ষা করুন।
সময় ও কঠিনতা: প্রাথমিক configuration review-এর জন্য প্রায় 20 মিনিট। স্তর intermediate। Provider তুলনার জন্য representative prompt দিয়ে অতিরিক্ত test দরকার।
Model name যা প্রকাশ করে না
Model identifier চাওয়া model নির্বাচন করে। Provider model implementation, token limit এবং tool-call parser-সহ inference service চালায়। Model-level benchmark প্রতিটি provider service-কে যাচাই করে না।
| Endpoint property | যা পরীক্ষা করবেন |
|---|---|
| Context length | Prompt, history, tool result এবং generation-এর স্থান |
| Maximum completion length | অনুরোধ করা task-এর output allowance |
| Supported parameter | Tool, structured output, sampling এবং reasoning control |
| Quantization | মূল release-এর তুলনায় ঘোষিত format |
| Pricing | Input, output, cache read এবং অতিরিক্ত charge |
| Serving behavior | Completion quality, parsing error, latency এবং retry |
Baseline routing সুস্থ candidate-দের মধ্যে কম দাম পছন্দ করে। OpenRouter inverse-square price weighting নথিভুক্ত করেছে। সরল উদাহরণে $1 candidate, $3 candidate-এর তুলনায় নয় গুণ selection weight পায়। এটি আপেক্ষিক weight, পরের request-এর নিশ্চয়তা নয়। Explicit order, sorting, caching এবং quality routing-ও selection বদলায়। Provider routing documentation দেখুন।
Price weighting আপনার workload-এর সবচেয়ে কম bill প্রমাণ করে না। উদাহরণে universal input/output mixture নেই। শুধু input price দেখে provider selection probability অনুমান করবেন না।
Context অনুযায়ী precision পড়ুন
Quantization কম representation ব্যবহার করে numeric value সংরক্ষণ করে। এর প্রভাব model, method এবং inference implementation-এর ওপর নির্ভর করে। কম precision test দাবি করে, কিন্তু label একাই provider মূল weight বদলেছে এমন প্রমাণ নয়।
GPT-OSS একটি স্পষ্ট উদাহরণ। OpenAI-এর gpt-oss-120b release documentation বলছে mixture-of-experts weight MXFP4 ব্যবহার করে এবং evaluation-এ একই quantization ছিল। সেই release-এর জন্য four-bit label সামঞ্জস্যপূর্ণ। এটি provider-এর অতিরিক্ত downgrade প্রমাণ করে না।
Upcasting সংরক্ষিত value-কে wider representation-এ রূপান্তর করে। আগে quantized checkpoint-কে BF16 করলে quantization-এ হারানো তথ্য ফিরে আসে না। উচ্চ precision-এর মূল checkpoint-কে four-bit করলে আলাদা পরিবর্তন হয়, যা পরীক্ষা করা দরকার।
| পর্যবেক্ষণ | সমর্থিত সিদ্ধান্ত |
|---|---|
| Native MXFP4 checkpoint | Four-bit expert weight release-এর অংশ |
| BF16 endpoint label | Wider reported format, ভালো উত্তরের প্রমাণ নয় |
| Unknown precision | Metadata অনুপস্থিত, hidden degradation-এর প্রমাণ নয় |
| Matching precision label | Equivalent serving behavior-এর জন্য যথেষ্ট evidence নয় |
একই label quantization difference-ও বাদ দেয় না। কোন tensor quantized, calibration কী, এবং কোন execution kernel ব্যবহৃত হয়েছে তা label বলে না। Bit depth-কে quality ranking না ধরে পুরো endpoint test করুন।
Token budget পরীক্ষা করুন
curl --fail --silent --show-error \
  'https://openrouter.ai/api/v1/models/openai/gpt-oss-120b/endpoints' \
  | jq '.data.endpoints[] | {
      name,
      provider_name,
      context_length,
      max_completion_tokens,
      supported_parameters,
      quantization,
      pricing
    }'
Endpoint API একটি model-এর provider metadata দেখায়। এই command-এর জন্য curl এবং jq দরকার। Service বাছার আগে
বর্তমান gpt-oss-120b endpoint response
দেখুন। Missing বা null field-কে unknown ধরুন, unlimited নয়। তুলনার সময় date-সহ local snapshot রাখুন।
5 October 2026-এর একটি check gpt-oss-120b-এর জন্য এই advertised limit দেখিয়েছিল। এগুলি metadata value, measured completion length নয়। Provider পরে এগুলি বদলাতে পারে।
| Provider | Context token | Maximum completion token |
|---|---|---|
| DigitalOcean | 128,000 | 4,096 |
| Novita | 131,072 | 32,768 |
| Together | 131,072 | 117,964 |
Context length এবং output length আলাদা limit। Long-context model-এরও উত্তরের জন্য যথেষ্ট স্থান দরকার। Conversation history, system instruction এবং tool definition user document-এর সঙ্গে সেই স্থান ভাগ করে।
Reasoning token সমর্থিত reasoning model-এ generation budget খরচ করে। ছোট allowance-এ অসম্পূর্ণ reasoning, কম visible output অথবা final answer-এর আগে termination হতে পারে। Usage ও finish reason দেখুন। Reasoning-token documentation এই budget ব্যাখ্যা করে।
Explicit max_tokens provider support-এর সঙ্গে মিলিয়ে দেখার জন্য router-কে requested output length দেয়। Measured task need এবং available context থেকে value বাছুন। অতিরিক্ত value eligibility কমায়, কিন্তু দীর্ঘ বা ভালো উত্তর নিশ্চিত করে না।
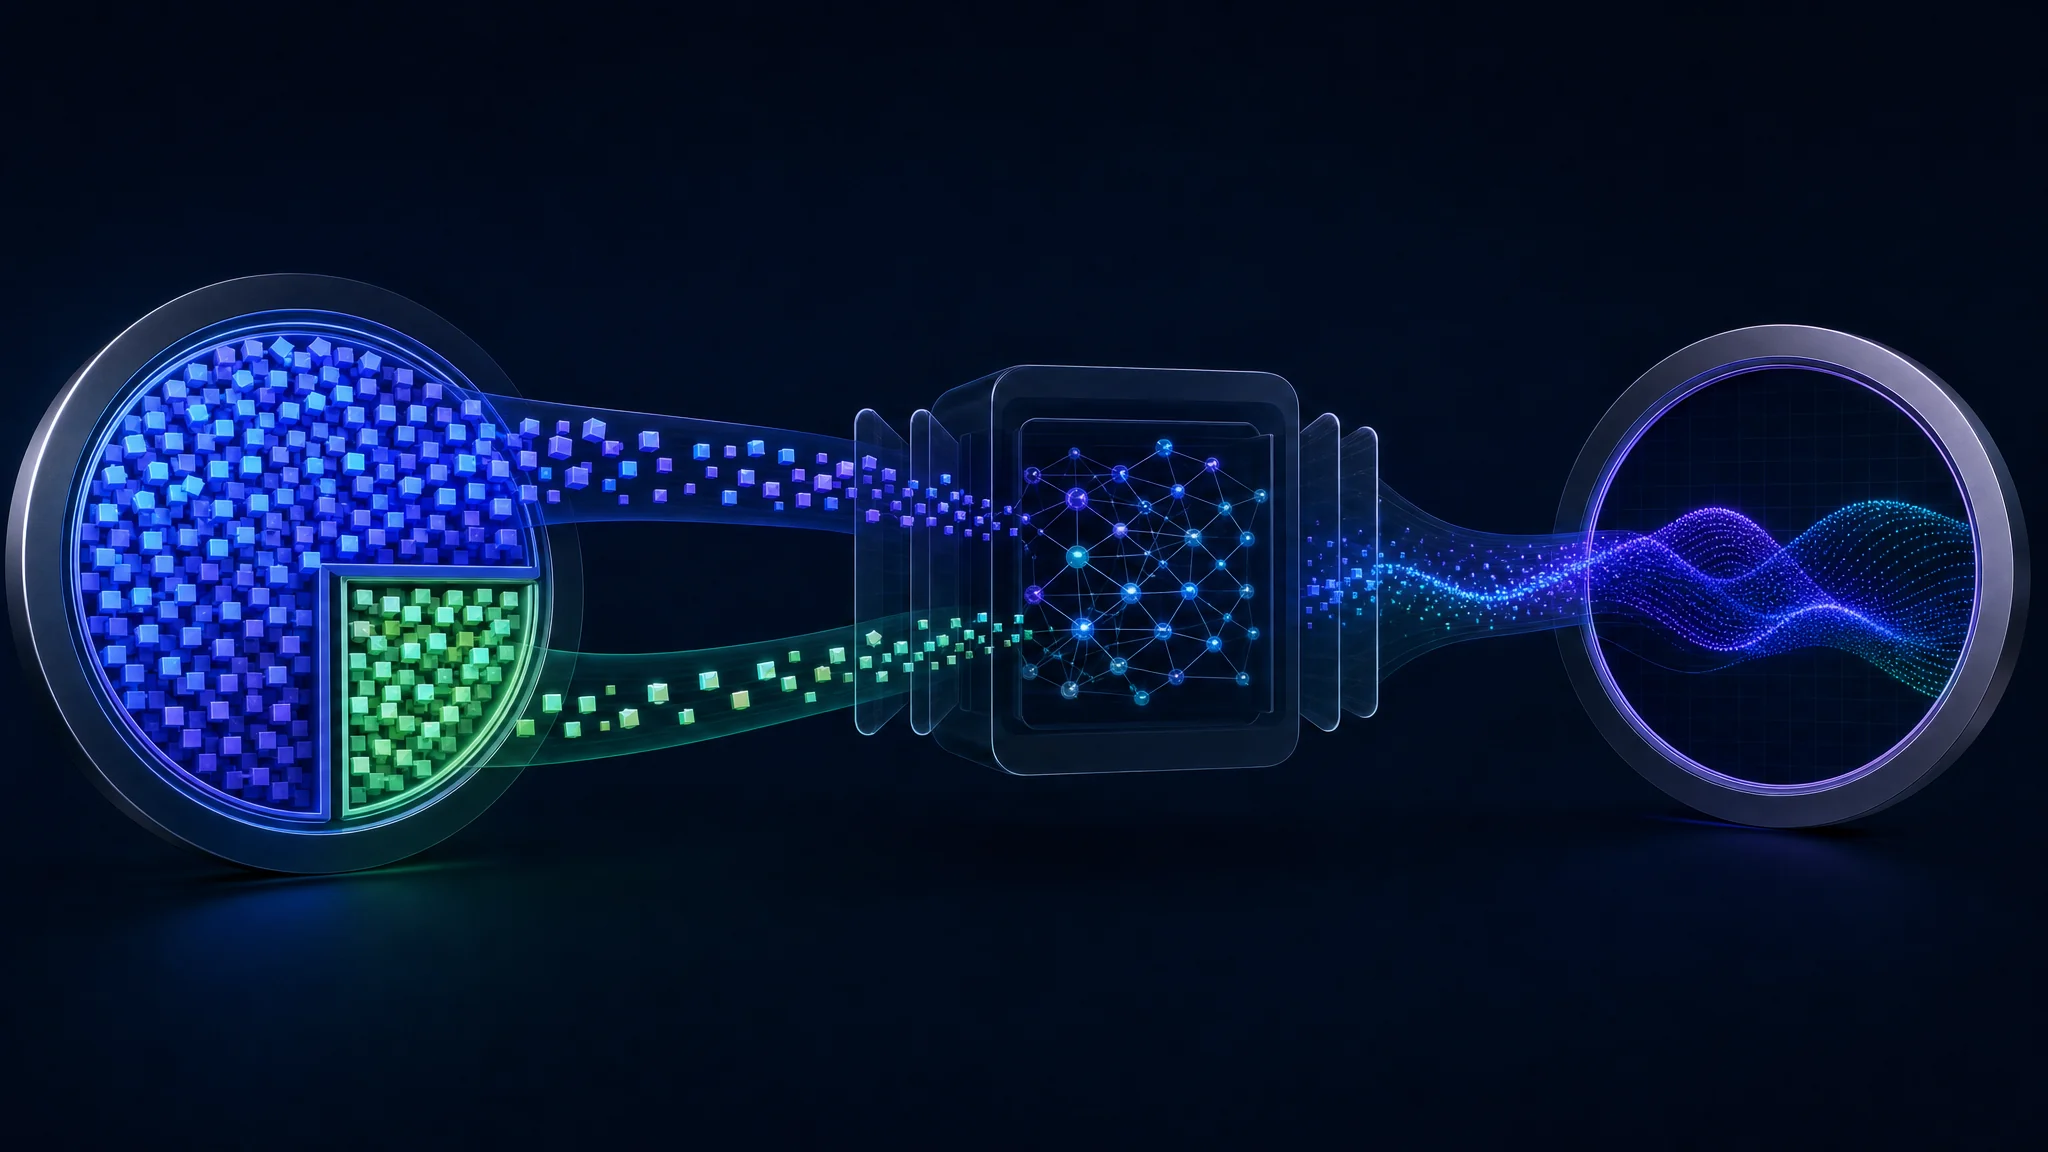
Conceptual token allocation, with reasoning and visible output sharing the completion allowance on supported providers
আপনার parameter বাধ্যতামূলক করুন
{
  "model": "openai/gpt-oss-120b",
  "messages": [
    {"role": "user", "content": "Explain the failure modes of a retry loop."}
  ],
  "max_tokens": 8192,
  "provider": {
    "require_parameters": true
  }
}
require_parameters-এর default false। Default routing-এ unsupported parameter endpoint বাদ দেয় না। OpenRouter বলছে provider unknown parameter ignore করে। true করলে declared support অনুযায়ী routing filter হয়।
Support metadata behavior guarantee করে না। Seed support ঘোষণাকারী endpoint-এ reproducibility test দরকার। Tool-capable endpoint-এ schema validation এবং application test দরকার। Filter পরিচিত incompatibility candidate set-এ ঢুকতে বাধা দেয়।
Provider ইচ্ছাকৃতভাবে pin করুন
{
  "model": "openai/gpt-oss-120b",
  "messages": [
    {"role": "user", "content": "Summarize the supplied incident report."}
  ],
  "max_tokens": 8192,
  "provider": {
    "order": ["REPLACE_WITH_VERIFIED_PROVIDER_SLUG"],
    "allow_fallbacks": false,
    "require_parameters": true
  }
}
Placeholder বদলান model provider listing থেকে নেওয়া provider slug দিয়ে। Real request-এ report পাঠান। Placeholder বদলানো না পর্যন্ত এটি runnable request নয়।
order preference স্থাপন করে। একা ব্যবহার করলে অন্য provider-এ fallback চালু থাকে। allow_fallbacks: false দিয়ে তালিকাভুক্ত provider-এ routing সীমিত করুন। কোনো provider request পূরণ না করলে বা available না থাকলে request ব্যর্থ হবে।
Endpoint variant-এর দিকে নজর দিন। Documented matching rule অনুযায়ী base provider slug একাধিক variant মেলাতে পারে। নির্দিষ্ট service configuration test-এ exact variant slug ব্যবহার করুন। প্রতিটি response-এর reported provider আবার পরীক্ষা করুন।
quantizations নামযুক্ত format-এর allowlist, numeric minimum নয়। "fp8"-সহ array matching FP8 endpoint বেছে নেয়। এটি স্বয়ংক্রিয়ভাবে BF16 বা বেশি bit-এর সব format যোগ করে না। আগে original checkpoint তুলনা করুন, তারপর evaluation সমর্থন করলে filter দিন।
Quality routing চালু রাখুন
{
  "model": "openai/gpt-oss-120b:exacto",
  "messages": [
    {"role": "user", "content": "Compare the two supplied incident reports."}
  ],
  "max_tokens": 8192,
  "provider": {
    "require_parameters": true
  }
}
Auto Exacto throughput, tool-call telemetry এবং benchmark ব্যবহার করে দুর্বল provider-কে পিছিয়ে দেয়। OpenRouter-এর March 2026 announcement GLM-5 tool-call error 88% কমে প্রায় 8% থেকে 1% হয়েছে বলে জানায়। gpt-oss-120b-এর জন্য 5.6% থেকে 3.5% পরিবর্তনের কথা বলে।
এগুলি provider-এর জানানো ফল, আপনার application-এর প্রতিশ্রুতি নয়। Tool-call validity JSON, name এবং schema মাপে। Syntax ঠিক থাকলেও task-এর জন্য সঠিক argument ও action দরকার।
Tool-সহ request পর্যাপ্ত provider coverage থাকলে default-এ Auto Exacto পায়। অন্য request-এ :exacto quality routing চালু করে। বর্তমান documentation tool use-এর পাশাপাশি summarization ও chat-এর জন্যও এটি সমর্থন করে।
sort: "price", :floor suffix এবং account-level default price sort Auto Exacto থেকে বের করে। Application setting এবং account preference একসঙ্গে দেখুন। Routing control মিলানোর আগে
Auto Exacto documentation
পড়ুন।
Workload cost হিসাব করুন
Input price একা অসম্পূর্ণ তুলনা। নিচের illustrative rate dollar per million token-এ দেওয়া। এগুলি arithmetic বোঝায়, current provider quote নয়।
| Illustrative endpoint | Input price | Output price |
|---|---|---|
| A | $0.03 | $16.00 |
| B | $0.42 | $1.32 |
Workload: 6 million input tokens + 1 million output tokens

A = 6 × $0.03 + 1 × $16.00 = $16.18
B = 6 × $0.42 + 1 × $1.32  =  $3.84

Per million combined input and output tokens:
A = $16.18 / 7 = $2.31
B =  $3.84 / 7 = $0.55
এই mixture-এ Endpoint A প্রায় 4.2 গুণ বেশি খরচ করে যদিও input price কম। A-এর 533-to-1 output/input ratio দুই rate-এর সম্পর্ক, total cost multiplier নয়। Input/output অনুপাত বদলালে ফল বদলাবে।
API pricing unit comparison table থেকে আলাদা। Endpoint API token প্রতি price দেয়। উপরের rate-এর সঙ্গে তুলনার আগে এক million দিয়ে গুণ করুন।
Prompt caching আরেকটি variable যোগ করে। Cached read, cache write এবং uncached input provider billing rule অনুযায়ী আলাদা হিসাব চায়। Repeated text cache hit নিশ্চিত করে না। Prompt caching documentation দিয়ে reported token count ও cost পরীক্ষা করুন।
Routing cache continuity-তে প্রভাব ফেলে। OpenRouter caching-এর জন্য sticky routing নথিভুক্ত করে, আর manual provider order অগ্রাধিকার পায়। Auto Exacto provider reorder করে এবং warm cache ব্যাহত করতে পারে। Policy বদলানোর আগে cache saving-এর সঙ্গে quality ও retry cost তুলনা করুন।
Accepted result-এর cost application-এর কার্যকর metric। Retry ও failed attempt-সহ মোট খরচ acceptance criteria পূরণ করা result দিয়ে ভাগ করুন। Token-বহির্ভূত charge আলাদা রাখুন। কম token rate বারবার ব্যর্থ task-এর ক্ষতিপূরণ নয়।
অসামঞ্জস্যপূর্ণ উত্তর নির্ণয় করুন
| লক্ষণ | প্রথম পরীক্ষা |
|---|---|
| ছোট বা অসম্পূর্ণ response | Finish reason, output allowance, reasoning usage |
| Document detail অনুপস্থিত | Submitted content, endpoint context limit, client truncation |
| Malformed tool call | Advertised support, tool schema, parsing behavior |
| ভিন্ন sampling behavior | Requested parameter এবং declared support |
| অপ্রত্যাশিত খরচ | Output volume, cache read, retry, provider change |
| Eligible provider নেই | Conflicting limit, allowlist এবং fallback restriction |
Response-এর generation ID সংরক্ষণ করুন। OpenRouter-এর generation metadata API provider identity, usage, cost এবং finish information দেখায়। Session ID related work group করে, কিন্তু এক request-এর lookup-এ generation ID-এর বিকল্প নয়।
Generation ID-এর পাশে request রাখুন। Model, provider preference, requested parameter, timestamp এবং response usage একসঙ্গে রাখুন। Routing, price বা endpoint metadata বদলালেও পরে quality বা cost comparison পুনরুৎপাদন করা যাবে।
একই শর্তে endpoint তুলনা করুন। একই prompt, tool, reasoning setting এবং token budget ব্যবহার করুন। কয়েকটি representative task-এ পুনরাবৃত্তি করুন। Incomplete response, invalid tool call এবং wrong answer আলাদা রাখুন।
Benchmark uncertainty গুরুত্বপূর্ণ। Epoch AI-এর analysis implementation, sampling এবং agent scaffold-এর কারণে variation বর্ণনা করে। একটি হতাশাজনক উত্তর persistent provider defect বা তার কারণ প্রমাণ করে না।
Endpoint routing walkthrough
আরও দেখুন: OpenRouter endpoint quality and routing discussion । নির্দিষ্ট price, limit বা provider comparison প্রয়োগের আগে endpoint listing আবার দেখুন।
পরবর্তী পদক্ষেপ
- একটি model-এর endpoint inspect করুন এবং workload-এর প্রাসঙ্গিক limit লিখে রাখুন।
- Routing policy বাছুন যেখানে parameter requirement ও fallback behavior স্পষ্ট।
- Representative task test করুন candidate endpoint এবং quality routing-এর বিরুদ্ধে।
- Accepted-result cost লিখুন latency, cache usage এবং failure category-র সঙ্গে।
- পরিবর্তনের পরে আবার পরীক্ষা করুন, model version, serving behavior বা provider price বদলালে।
আরও AI fundamentals-এর জন্য Basic AI Concepts পড়ুন। Agent permission এবং validation control-এর জন্য Securing AI Systems পড়ুন।
Related Posts